Resources · Technical
Which AI Crawlers Exist, and How to Check Their Access
7 min read · updated October 28, 2026
Retrieval agents · allow
Training crawlers · your call
The AI crawlers covered here are OpenAI’s OAI-SearchBot, GPTBot and ChatGPT-User; Anthropic’s ClaudeBot, Claude-SearchBot and Claude-User; Perplexity’s PerplexityBot and Perplexity-User; and Google’s Googlebot, which covers AI Overviews and AI Mode, plus the Google-Extended robots.txt token.
AI services use agents for search indexing, training collection and user-requested retrieval. Check the named provider's controls before changing access: training and search rules have different scopes, and user-requested fetches do not share one robots.txt policy.
Start with the public pages you want buyers to find. Check whether the relevant service can retrieve their content, then inspect answer records for mentions or citations.
The provider information below was checked on 8 October 2026. It covers OpenAI, Anthropic, Perplexity and Google. It is a practical reference for these systems, not an exhaustive list of every crawler.
Distinguish three purposes
Search-index crawling collects pages for a search system. Check the agent and access policy used for that provider's index.
Training collection gathers material that may contribute to future models. Decide your training preference separately, using the provider's stated control and scope.
User-requested retrieval visits a page as part of an action someone asked the service to perform. Check the provider's policy for those requests rather than inferring it from an automated crawler's rules.
Some controls cover more than one purpose. Check the scope of the particular token.
| Purpose | What to investigate | Access decision |
|---|---|---|
| Search | Indexing and answer retrieval | Public content intended for discovery |
| Training | Collection for model development | The documented training preference |
| User request | A fetch initiated for a person | The provider’s user-fetch policy |
Read each provider’s documentation. Google-Extended also covers specified grounding uses.
OpenAI: search, training and user actions
| Agent | Documented purpose | Access point to check |
|---|---|---|
| OAI-SearchBot | ChatGPT search discovery | robots.txt and published source IP ranges |
| GPTBot | Collection that may support model training | Independent training preference |
| ChatGPT-User | Certain user-requested actions | robots.txt may not apply |
OpenAI says OAI-SearchBot and GPTBot settings are independent. Sites opting out of OAI-SearchBot are excluded from ChatGPT search answers, but may still appear as navigational links. It also says ChatGPT-User does not determine Search eligibility. OpenAI crawler documentation
Do not describe a ChatGPT-User robots.txt block as a guaranteed prohibition on every user-initiated read or citation. The published policy contains that caveat.
Anthropic: check each named bot
| Agent | Documented purpose | Access point to check |
|---|---|---|
| ClaudeBot | Collection potentially contributing to training | Training preference |
| Claude-SearchBot | Search indexing | Search access |
| Claude-User | Retrieval requested by Claude users | User-directed access |
Anthropic states that its bots honor robots.txt directives and do not attempt to bypass CAPTCHAs. Its policy describes distinct consequences for disabling its search and user-request agents. Anthropic crawler policy
Use Anthropic's instructions for Anthropic's agents. A caveat documented by another provider is not evidence that Claude follows the same behavior.
Perplexity: index and user-request agents
| Agent | Documented purpose | Access point to check |
|---|---|---|
| PerplexityBot | Search discovery and links | robots.txt and published source IP ranges |
| Perplexity-User | User-requested retrieval | Generally ignores robots.txt for those fetches |
Perplexity describes its user-request agent as separate from automated crawling and training collection. Its documentation recommends checking both the agent and published IP ranges when configuring firewall access. Perplexity crawler documentation
Compare the policy with actual request records. A robots declaration does not tell you what the server returned.
Google: Search and Google-Extended have different scopes
Google says Googlebot access controls apply to Search, including AI Overviews and AI Mode. Search preview controls such as nosnippet, data-nosnippet, max-snippet and noindex address how content can appear. Google's AI features guidance
Google-Extended is a robots.txt control token, not a separate HTTP user-agent string. Google's current documentation describes its scope as future Gemini-model training and grounding in specified Gemini and Vertex AI products. It says the token does not affect inclusion or ranking in Google Search. Google's crawler reference
Consequently, “block Google-Extended to block all Google AI uses” is too broad. So is a description that limits its scope to training alone. Read the specified products and uses before making that decision.
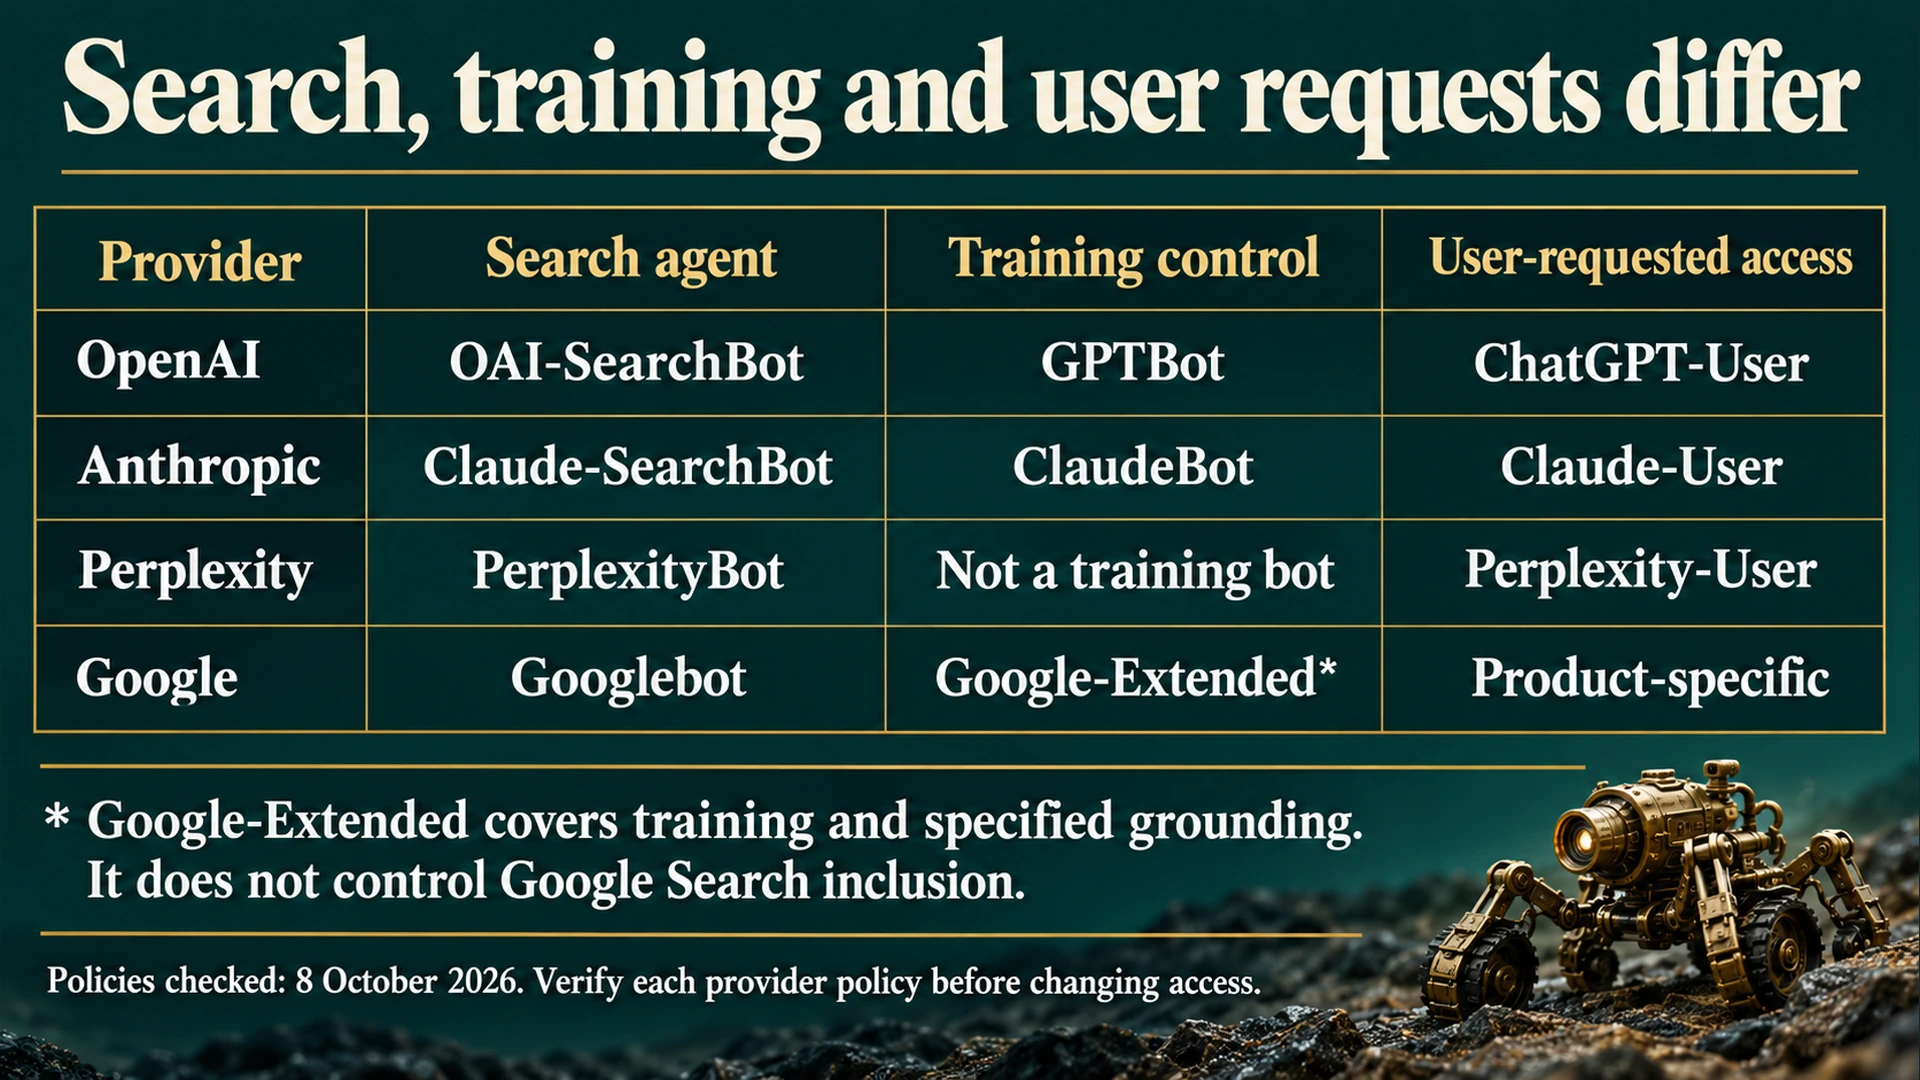
Provider policies checked on 8 October 2026. Google-Extended also covers specified grounding uses and does not control Google Search inclusion.
Decide the access goal before editing rules
Write down the public pages you want eligible for search or answer retrieval. Then record the training preferences and any pages that must remain restricted. Keep authentication and private content protected regardless of marketing goals.
Avoid copying a generic allowlist over an existing robots.txt file. First inspect its groups and paths and check how the relevant crawler interprets them. A small edit can affect pages beyond the one you are investigating.
Use a planning matrix before asking someone to change the configuration:
Provider and documented agent or token:
Purpose and official source:
Public pages intended to be accessible:
Training preference:
Current robots rules:
Current firewall or CDN behavior:
Authentication or other restrictions:
Proposed change and expected scope:
Verification needed after the change:
This records an access decision. It is not a ready-to-apply configuration and does not authorize weakening a production firewall.
Inspect the response, including its contents
Review server or CDN records for relevant requests. Collect the timestamp, URL, claimed agent, source IP, response status and rule that handled the request where those records are available.
A 403 can identify an access refusal. A 200 establishes a successful HTTP response, but inspect whether that response contains the intended page or an interstitial, challenge or empty shell. The status alone does not settle whether useful content reached the requester.
Check important pages individually. A working homepage does not establish that a product page or resource article is accessible under the same conditions.
If you do not have logs or a reliable response record, say what remains unverified. A missing citation does not identify a firewall problem without supporting evidence.
A 200 response can contain a challenge or empty shell. A spoofed user-agent probe does not establish real provider access.
Verify identity before granting special access
A request's user-agent string can be copied by another program. Google's crawler reference warns that the string can be spoofed and links to verification guidance.
Verify the requester using the provider's current method or published IP information. Limit any exception to the verified identity and the public content it needs.
A manual request with a bot's name can test how your server treats that name. It does not prove a real provider request will take the same route or receive the same result. Label such a probe accurately in the access record.
Separate an access fix from a visibility result
After an approved change, verify the expected response and preserve the before-and-after evidence. Then examine answer observations separately. A successful fetch does not guarantee indexing, a citation, a recommendation or a visit.
Keep the buyer questions stable when assessing subsequent mentions. Record dates, platforms and modes, and preserve missing observations rather than treating them as negative answers. The buyer-prompt guide and visibility-score guide explain the measurement context.
If the page is accessible but remains absent from answers, investigate the question, relevant sources and competing answers rather than assuming more access changes will solve it.
A read-only access-review checklist
Page and provider:
Official agent purpose and policy checked on:
Current robots.txt reviewed:
Current server/CDN rules reviewed:
Provider identity verification available:
Real request record available:
Response status and page contents:
Problem established by evidence:
What remains unverified:
Proposed correction, if needed:
Separate answer-observation record:
Date the access record and revisit the provider's documentation when the policy changes. After any approved correction, check the response again and keep answer observations separate.
Related guides
Citations (6)showhide
See who AI recommends in your category
The free scan asks ChatGPT three of your buyers' questions and shows whether you're in the answer, in about a minute.
Run the free scan →Go further with daily AI tracking, SEO and competitor paid ads research, and recommendations to help you act. Explore the plans.