Resources · Playbook
How to Find the Prompts Your Buyers Actually Ask AI
7 min read · updated October 8, 2026
The five shapes buyer questions take
Round-up
“Best CRM in 2026?”
Situational
“Best CRM for a 5-person agency”
Outcome
“Track projects without standups?”
Budget
“Cheapest CRM that is reliable”
Trust
“What do people recommend on Reddit?”
Build your prompt set from buyer problems and requirements you can document. For each question, record the exact wording, evidence source and monitoring settings. Separate unbranded discovery questions from questions that name your brand.
An AI visibility score depends on the questions being tracked. A set built around your brand name answers a different question from a set asking which suppliers solve a buyer's problem. Both can be useful, but they need separate interpretation.
The worksheet below documents the buying situations you choose to monitor. It does not measure every question asked in your market.
Begin with a decision a buyer needs to make
Write down the task, the person making the decision and the requirements that affect their choice. “Appointment software” is a category. “An appointment system for a clinic with three practitioners who share rooms” is a buying situation.
Use language found in real sources where you have permission to use it. Relevant material can include sales-call notes, support questions, search-term reports and public discussions. Record where the wording came from without copying private customer details into a tracking prompt.
Search research can suggest needs to investigate. It does not establish how often people ask the equivalent question in an AI assistant. Google's search terms report documentation describes searches associated with ads; those observations belong to that search context.
Label any question you devised as a hypothesis. Test whether it is useful, while keeping it separate from recorded buyer wording.
Fictional planning hypothesis from the article, not collected query data. Verify the service and geography before using it.
Use five question shapes as a planning aid
The existing Geofound buyer-prompt guide organizes questions into round-up, situational, outcome, budget and trust forms. Use those forms to check coverage rather than treating them as a measured taxonomy of every buyer's behavior.
| Shape | Question to consider |
|---|---|
| Round-up | Which providers or products serve this category? |
| Situational | Which option fits this buyer's constraints? |
| Outcome | How can the buyer complete a particular task? |
| Budget | Which options fit the stated cost requirements? |
| Trust | What evidence supports confidence in an option? |
Ten to twenty selected questions can be a manageable starting set for a small team, but that count does not guarantee representativeness. Use fewer if they cover your documented buying situations.
Separate discovery, reputation and comparisons
Label each prompt by what it investigates.
Discovery prompts leave your brand out and ask about a need or category. They help you observe which names arise when the question does not supply yours.
Reputation prompts name your brand and ask about it. They can reveal how an assistant describes you, including inaccuracies. They do not measure unaided discovery.
Comparison prompts name alternatives and ask for differences. They are useful when the comparison reflects a real buyer decision. Their brand mentions are partly built into the question, so do not blend them into the discovery score.
Keep these groups separate in your analysis. A rise in reputation-prompt mentions cannot be interpreted as improved discovery if the questions themselves already contain your name.
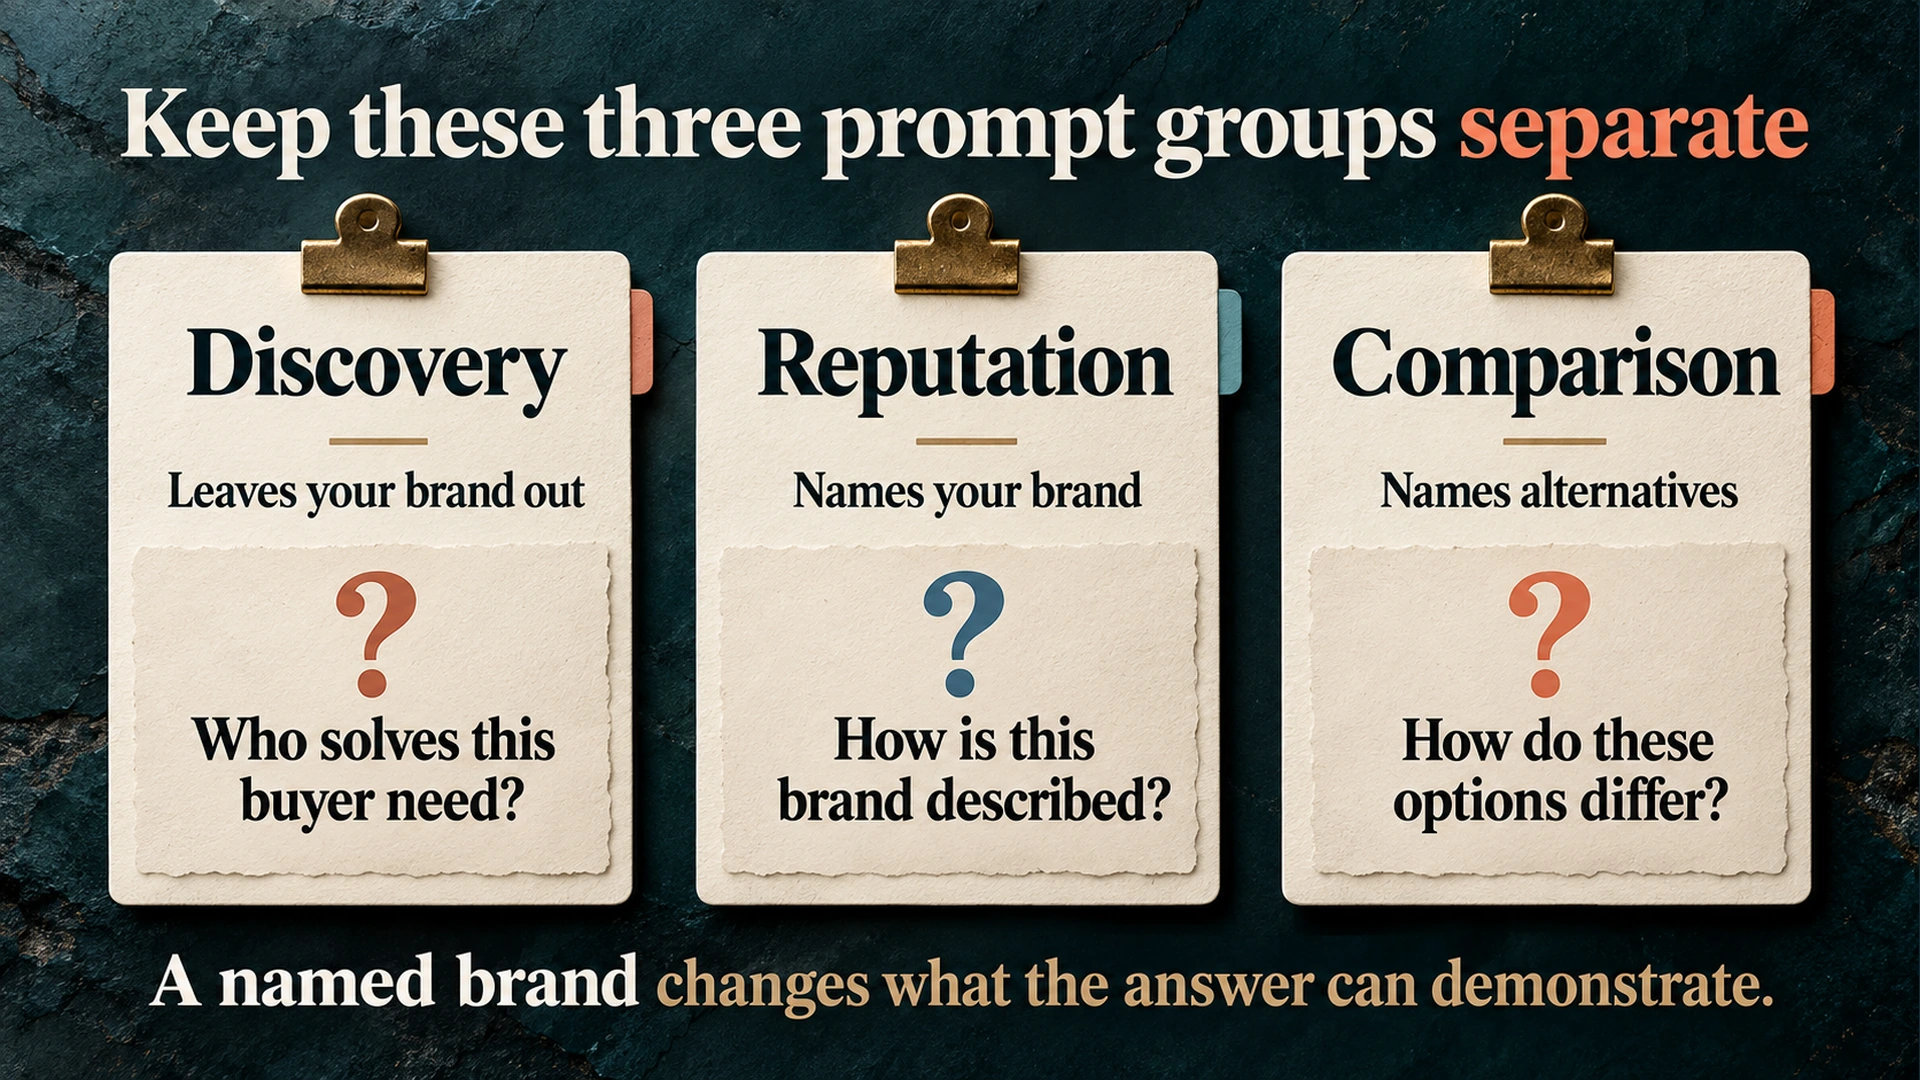
Keep the groups separate because brand names supplied in a question change what an answer can demonstrate.
Fill in one row for each prompt
Use this schema in a spreadsheet or plain-text file:
Prompt ID:
Group: discovery / reputation / comparison
Question shape:
Buyer task:
Exact prompt wording:
Evidence source and date, or hypothesis label:
Relevant geography and language:
Platform, model or mode where identifiable:
Browsing or search setting where identifiable:
Prompt-set version:
Reason for inclusion:
Known limits:
Keep the exact wording separate from your description of the task. It is the wording that needs to remain stable for a repeat comparison.
Geography belongs in a prompt when it affects the purchase. A repair service is tied to an area. A software question may instead depend on language, supported currencies or data-location requirements. Do not add a location merely because it makes the prompt look more specific.
Worked examples for two businesses
These examples are fictional planning hypotheses. They are not customer quotations, collected query data or reported model answers.
| ID | Business and task | Illustrative prompt | Group and shape |
|---|---|---|---|
| S01 | Local repair service; find an available provider | Who repairs commercial coffee machines in Bristol? | Discovery; situational |
| S02 | Local repair service; understand the buying decision | What should a small cafe check before choosing a coffee-machine maintenance service? | Discovery; outcome |
| A01 | Software; coordinate shared rooms | Which appointment systems suit a clinic with three practitioners sharing treatment rooms? | Discovery; situational |
| A02 | Software; compare cost for a defined team | How should a three-practitioner clinic compare appointment software costs, including reminders? | Discovery; budget |
Before adding S01 to a real set, confirm that the business serves that location and provides that repair. Before adding A01, confirm that shared rooms matter to the intended customers. A prompt can be well written and still be irrelevant to the offer.
S02 may produce advice without naming providers. Keep it if understanding that advice is part of your objective, but do not expect it to behave like a direct supplier-list question. Record the question's purpose rather than forcing every answer to contain brands.
Test the prompt's usefulness
Inspect an answer to see whether the question produces information relevant to the decision you want to observe. Keep the prompt, response date and mode with that test.
If the answer is too broad, identify the missing buyer requirement before rewriting the question. If it is already useful, avoid rewriting it simply to get your preferred brand list.
A trial response is a check of the prompt's behavior in that setting. It is not proof of common buyer wording or stable visibility. Do not select questions only because they happen to mention your business once.
Keep a versioned prompt set
Give the initial set a version, such as clinic-discovery-v1, and save its exact rows. Record changes in a separate log:
| Date | Change | Reason | Effect on comparison |
|---|---|---|---|
| Illustrative date 1 | Added a room-sharing question | New customer requirement to investigate | New prompt starts a separate baseline |
| Illustrative date 2 | Corrected the tracked service area | Previous location did not match the offer | Compare revised prompt from the change onward |
| Illustrative date 3 | Switched search mode | Monitoring setup changed | Annotate the series and review comparability |
Preserve earlier wording when a question changes. Annotate the series so a reviewer can see where the inputs changed.
When your business changes, update the set deliberately. A stable but obsolete prompt is not useful merely because it produces a longer history.
Record the answer and missing observations
Save enough information to inspect the actual result:
Observation date and time:
Prompt ID and set version:
Platform and mode:
Status: completed / failed / missing
Brand mention and context:
Cited URL, if any:
Incorrect or unsupported claims:
Competitors mentioned:
Response record location:
Reviewer note:
A failed request is missing evidence. It is not automatically an answer that omitted your brand. State how missing observations are handled before calculating a percentage.
For a simple illustrative count, if a brand appears in six of twenty completed observations, its observed mention rate is 30% for that defined set. If five other requests failed, report those failures separately. This calculation is a worksheet example, not a description of Geofound's implementation or a market-wide visibility estimate.
| Field | Record | Do not infer |
|---|---|---|
| Prompt version | Exact wording and version | That changed wording is comparable |
| Answer | The response or a missing observation | That missing data means no mention |
| Source | Any citation actually present | That a mention necessarily has a citation |
| Context | Platform, mode and date | That one answer represents every mode |
This is a recording worksheet, not a chart of measured customer results.
Read changes in the context of the sample
Before attributing a change to an article or website edit, check the prompt set, engines, modes, dates and missing observations. Keep the actual answers available so you can examine what changed.
The visibility-score guide explains why sample size and repeated observations matter. A small change or a before-and-after comparison does not establish its cause by itself.
Keep mentions, citations, visits and sales as separate measures. The question set describes what you observed in answers. It cannot alone tell you how many buyers visited or purchased.
Save the prompt worksheet and version log together. Each tracked question needs a reason for inclusion and a record of later changes.
Related guides
Citations (1)showhide
See who AI recommends in your category
The free scan asks ChatGPT three of your buyers' questions and shows whether you're in the answer, in about a minute.
Run the free scan →Go further with daily AI tracking, SEO and competitor paid ads research, and recommendations to help you act. Explore the plans.